Well that session was exactly what I wanted! Open linked data has been on my watch list since 2010 after seeing OpenCalais demoed at that years VALA
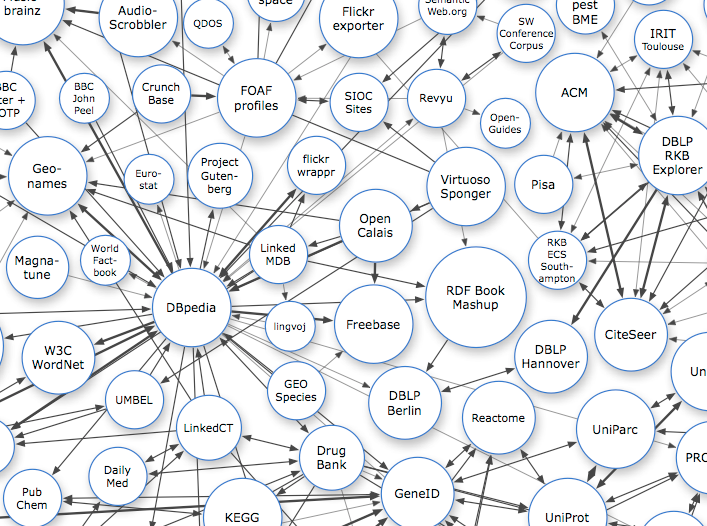
It was great to see under the hood and spakfil my limited understanding of what it all meant. I liked that Tim and Paul be aware of 'Linked Open Data (LOD) Paralysis' (see image below) and keep dragging us back to practical uses.
So I now know RDFa is the defacto standard, that Google, Microsoft Bing and Yahoo actually cooperated. Handcrafting your own linked data in html code gave us an object lesson in why you wouldn't only create this sort of markup using computers. But as the 'other' Tim and Paul point out - libraries already have this information stored in databases in a highly structured format, it just that once we publish it to the web we throw the structure out so it looks nice on a page. Generating this same content with embedded Linked Open Data (LOD) from these databases shouldn't be hard.
LOD maintains the structure of the data (so it makes sense to computers) without changing how it looks (which makes sense to humans).
'But why would we care what those dumb old computers think? ' I hear you ask. Because once computers understand that a particular text string is a person, building, organisation or tea cozy, with a bunch of attributes, that may also be shared with other 'things' we make clearly visible connections that are invisible or buried to us with unstructured information.
It's early days but as LOD becomes the default the possibilities expand. If you want to see an example of it search google - the panel on the right hand side is pulling that information from various sites using LOD.
The other take out was search engines prefer LOD enriched sites, paying attention to content that was just a long string of characters to be ignored by Google (with 'normal' pages Google mostly relies on HTML title tag. LOD enhanced content opens up discovery.
Using the resource tag is like a web-based authority list. If you link a data element to verified source your item is automatically linked to every other data element anyone else has linked to that same resource. Which in turn expands the number of 'attributes' that item has. Bear with me with this tortuous example. But say you link a publication's author to a verified linked data target. And say someone else links a player in a list of former Seattle Seahawks greats to that same person. Then without any human intervention a third party locating the book can see that the author once played in the Superb Owl (HT @StephenAtHome)
Paul and Tim list a bucket load of resources here: http://t.co/RiIlQk4s8J
dbpedia is the semantic web mirror of wikipedia and common datastore the resource tag is pointed at. It might help to get a sense of just how much information is available about a 'thing' but just taking a look at the entry for J.K Rowling (courtesy of the Fantales exercise) scroll down to see the extent of informational attributes recorded for the author.
What does it mean for us? Well the biggest buckets of structured data we control directly are our catalogue and eprints - neither of the frontends we provide for them (Tropicat & ResearchOnline@JCU) currently have any facility for integrating LOD - but perhaps we can encourage developments in that area from the vendors, likewise Summon might be pushed in that direction, and Tim and Paul were clear that Trove was moving toward increasing LOD - initially driven because 76% of Trove referrals come from Google, and LOD promotes your resources in Google. Trove harvests our eprints through OAI-PMH (which is highly structured XML) so we benefit from their work. Also on my wish list is LOD capability in any new CMS JCU acquires.
An ongoing postulation about Library Technologies at James Cook University,
primarily aimed at the staff of the library at James Cook University and curious
people working with IT in academic and research libraries around the world
Monday, February 3, 2014
Saturday, November 30, 2013
And another fail scenario for EZproxy: GeoScienceWorld and the Google Maps API
This issue resolved by GSW December 8
To borrow a line from Jonathan Rochkind's Bibliographic Wilderness 'EZProxy is terrible, it's just the best we've got.'
I don't think it's terrible but it's always been a pain that TOC services don't work off campus and that RSS feeds occasionally don't work at all, but this week I got a something new.
GeoScienceWorld's search interface includes a world map that uses the Google Maps API. - and if we access the search page via ezproxy (and we default all users through EZProxy - even on campus) Google Maps refuses to serve data because the API Key is not registered for use in our domain (i.e. it works if you strip out the EZProxy suffix 'elibrary.jcu.edu.au')
This is the message
If we remove the proxying from the link in our A-Z of database pages it will work for on campus users but off campus users won't get access to the website at all because of the IP restriction.
I haven't worked with Google Maps API - but my reading of their authorisation doco suggests there isn't a simple workaround. The prevention of other sites using your app is intentional - in a library context it's a barrier. I'm going to guess that GSW isn't interested in registering every subscriber's EZProxy domain even if it's possible.
Will be getting our people to talk to their people to see what can be done, and if anyone else has mentioned it.
People have suggested that in the future the EZProxy fail situations might be resolved by Shibboleth, or some other middle tier authentication broker. Right now I'm suggesting that power users use the VPN and strip the EZProxy suffix. Being a specialist resource most users should be easy to define (Earth Sciences), and therefore easy to inform of the problem and workarounds.
Will comment if GSW get back to us.
To borrow a line from Jonathan Rochkind's Bibliographic Wilderness 'EZProxy is terrible, it's just the best we've got.'
I don't think it's terrible but it's always been a pain that TOC services don't work off campus and that RSS feeds occasionally don't work at all, but this week I got a something new.
GeoScienceWorld's search interface includes a world map that uses the Google Maps API. - and if we access the search page via ezproxy (and we default all users through EZProxy - even on campus) Google Maps refuses to serve data because the API Key is not registered for use in our domain (i.e. it works if you strip out the EZProxy suffix 'elibrary.jcu.edu.au')
This is the message
Google has disabled use of the Maps API for this application. This site is not authorized to use the Google Maps client ID provided. If you are the owner of this application, you can learn more about registering URLs here: https://developers.google.com/maps/documentation/business/guide#URLsThis happens as soon as you try to access GSW's search because the map is built into the search form - even if you don't want to use it. That message appears in a dialog box - it scares off most users, who don't realise clicking 'OK' will get you to vanilla searching (sans Map) but that gives the impression search might be broken because the map disappears leaving a worryingly blank blue square.
If we remove the proxying from the link in our A-Z of database pages it will work for on campus users but off campus users won't get access to the website at all because of the IP restriction.
I haven't worked with Google Maps API - but my reading of their authorisation doco suggests there isn't a simple workaround. The prevention of other sites using your app is intentional - in a library context it's a barrier. I'm going to guess that GSW isn't interested in registering every subscriber's EZProxy domain even if it's possible.
Will be getting our people to talk to their people to see what can be done, and if anyone else has mentioned it.
People have suggested that in the future the EZProxy fail situations might be resolved by Shibboleth, or some other middle tier authentication broker. Right now I'm suggesting that power users use the VPN and strip the EZProxy suffix. Being a specialist resource most users should be easy to define (Earth Sciences), and therefore easy to inform of the problem and workarounds.
Will comment if GSW get back to us.
Monday, November 25, 2013
Google Scholar, WoS and Informit
Not sure why Google Scholar has suddenly intersected with my job again after a seeming hiatus. The renewed activity seems to indicate Google is committed to developing and maintaining Scholar - (have already seem some conspiracy theory postings about this being the next step in googlizing the information universe now that the Google Book law suit has been dismissed)
Anyway at least I have a theme uniting a bunch of thoughts.
They've introduced:
All you need for this functionality is a Google Account.
TR's email stating that this was all about improving user experience didn't gel with my version of reality and I suspected (wrongly, I assume) that this was an example of Google being evil - that TR had to be exclusive to Google to jump on their bandwagon. But a couple of days of whingeing tweets and blogs and listserv emails (and who knows what unpublic communication) from libraryland and TR announced that it would continue working with the other discovery layers. That the new announcement was so quick seemingly disproves there was any exclusivity agreement with Google - it seems it must have been a business decision to lessen their workload and thus increasing profit - pretty sure no discount would have come had they proceeded with discontinuing DL support.
Anyway, except for some raised blood pressure no harm done. Now we wait and see how Google Scholar uses the WoS data. I'm pretty sure it will still require an institutional subscription for a user to see the data. I assume IP restriction will be used, so citation counts will appear much like our Link Resolver appears if you access Scholar on campus or through EZproxy.
Given that Scholar already has citation counts it may be that WoS will simply replace whatever Scholar is doing to create those counts.
Not so sure if users will able to attach themselves to an institutional subscription without EZproxy (like you currently can in your Scholar Settings).
The Summon developers announced that the Informit suite is now included in their unified index. I found a problem with full text links to Find It@JCU for previous titles/ISSNs, and I wanted to see if Scholar was building OpenURLs that worked - only to discover that Informit is a 'special case' in Scholar. If you click on the title of a citation harvested from Informit in Scholar you are taken to full text in Informit - works great if you are on campus. Not sure what happens if you aren't.
I've submitted a request to RMIT Publishing asking that they work with Scholar to provide some sort of visual indication in the SERP that fulltext is available (it looks like a typical citation only hit - there is no link in the right column to either the link resolver or a URL)
Anyway at least I have a theme uniting a bunch of thoughts.
Google Scholar as Research Platform
I don't know when it happened but Google Scholar has upped the ante on its functionality and is horizontally integrating services provided to researchers.They've introduced:
- A web-based citation manager (My Library)
- A quasi research portfolio (a list of your research output that appears in Scholar)
- An alerting service (you get emails when new items match your criteria)
- H5 metrics
All you need for this functionality is a Google Account.
WoS (Wusses Out Speedily)
First there wast Thomson Reuter's (TR) announcement last week that they were going integrate Web of Science (WoS) with Google Scholar and simultaneously stop integrating it with the other 'discovery layers' (Summon, Primo and Ebscohost).TR's email stating that this was all about improving user experience didn't gel with my version of reality and I suspected (wrongly, I assume) that this was an example of Google being evil - that TR had to be exclusive to Google to jump on their bandwagon. But a couple of days of whingeing tweets and blogs and listserv emails (and who knows what unpublic communication) from libraryland and TR announced that it would continue working with the other discovery layers. That the new announcement was so quick seemingly disproves there was any exclusivity agreement with Google - it seems it must have been a business decision to lessen their workload and thus increasing profit - pretty sure no discount would have come had they proceeded with discontinuing DL support.
Anyway, except for some raised blood pressure no harm done. Now we wait and see how Google Scholar uses the WoS data. I'm pretty sure it will still require an institutional subscription for a user to see the data. I assume IP restriction will be used, so citation counts will appear much like our Link Resolver appears if you access Scholar on campus or through EZproxy.
Given that Scholar already has citation counts it may be that WoS will simply replace whatever Scholar is doing to create those counts.
Informit
I've submitted a request to RMIT Publishing asking that they work with Scholar to provide some sort of visual indication in the SERP that fulltext is available (it looks like a typical citation only hit - there is no link in the right column to either the link resolver or a URL)
![]() |
| Informit citation without full text indicator |
Labels:
Databases,
Fulltext Publishers,
Google Scholar
Wednesday, August 7, 2013
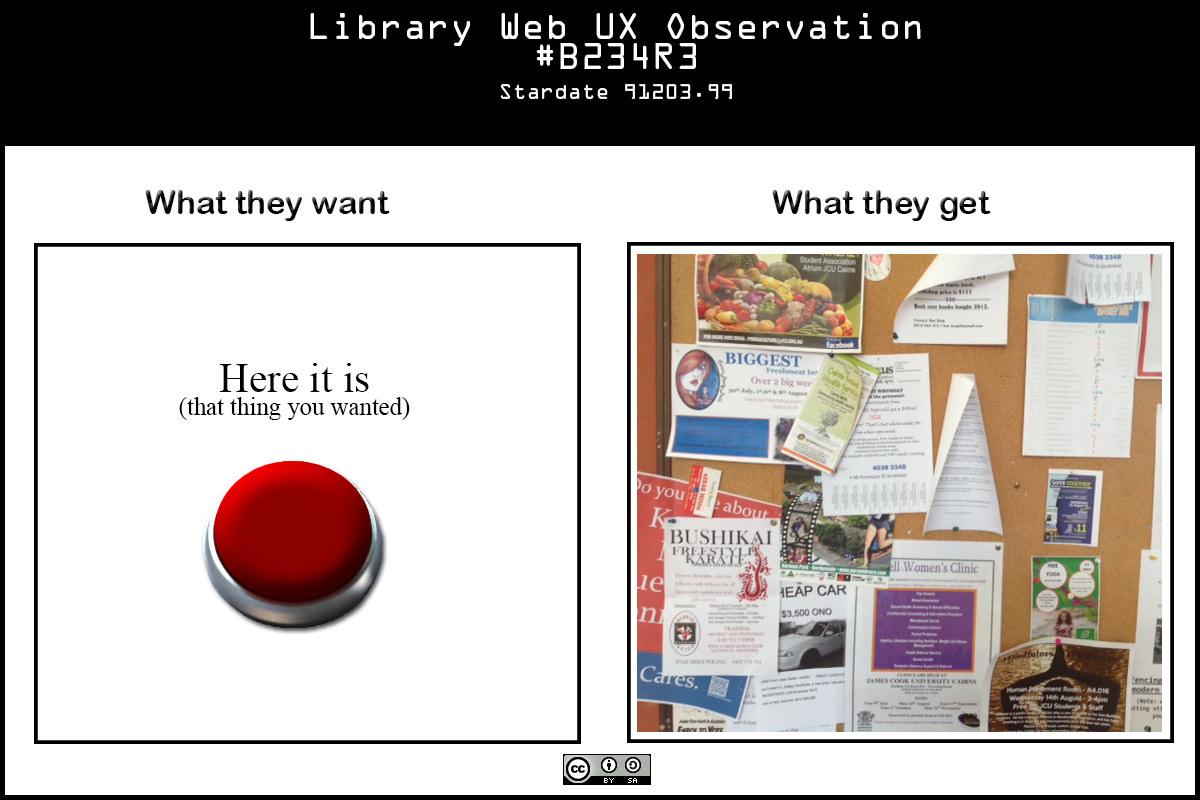
My UX Frustrations Visualised
I am turning into a cranky old man - I can only apologise to my colleagues for having to put up with my tirades. They seemed to like Steve Krug's 'Don't Make Me Think', but the home page remains a regular battleground. I know compromises have to be made - but the compromises always seem to cost the users. So to vent some steam and publicly apologise for my crankiness I resort to faux visualisation:
Monday, July 29, 2013
Shifting shores of digital music
Just some random thoughts sparked by seeing the 'Spotify is killing iTunes' story in the Australian Financial Review that got a mention on ABC24 this morning.
First it was underlining what you read in the tech press about the future all the time, i.e. things are changing quicker.
That the iTunes store has moved from being the snarky young punk the of music distribution business to an overlord in decline, in barely a decade, is semi-startling.
The ultra-personalised digital world is here, well it's been here for a while but now it's slapping us in the face.
There are some pretty obvious parallels between the ebook and music publishing businesses. What significance for libraries does the apparent coming triumph of streaming/rental over download/own have for us?
Does our ingrained love of the book (the owned object containing fixed information) have as much cachet with Gen Z as it does with boomers? Will information be completely fluid, will all knowledge be a constantly moving mashup? Maybe it is already. Maybe it always was.
Extrapolating on the moves:
A vision where a cadre of multitalented individuals visit tiny online communities, opening their ears to great sounds from far off (out) places and moving to the next community. Ladies and gentlemen, I give you the digital troubadour.
First it was underlining what you read in the tech press about the future all the time, i.e. things are changing quicker.
That the iTunes store has moved from being the snarky young punk the of music distribution business to an overlord in decline, in barely a decade, is semi-startling.
The ultra-personalised digital world is here, well it's been here for a while but now it's slapping us in the face.
There are some pretty obvious parallels between the ebook and music publishing businesses. What significance for libraries does the apparent coming triumph of streaming/rental over download/own have for us?
Does our ingrained love of the book (the owned object containing fixed information) have as much cachet with Gen Z as it does with boomers? Will information be completely fluid, will all knowledge be a constantly moving mashup? Maybe it is already. Maybe it always was.
Extrapolating on the moves:
- from ownership, to rental, to instant access;
- from album to song;
- from labels dictating taste on large scale to an explosion of gatekeepers directing increasingly specialised taste groups;
- from music news from formal publishing and broadcast channels to social media-enhanced word-of-mouth
- from the recording being the income generator to being merely a promotional tool for gig attendance
A vision where a cadre of multitalented individuals visit tiny online communities, opening their ears to great sounds from far off (out) places and moving to the next community. Ladies and gentlemen, I give you the digital troubadour.
Thursday, July 18, 2013
Random thought: The limits of Google Analytics - it's just data, not information
I'm still wading through Google Analytics to get an idea of how the web site is used so I can have some 'evidence-based' proposals for the site home page and persistent navigation.
One thing that I'm pondering after my last blog post is referrals from Search Engines. If a page is linked to much more often from a search engine results page (SERP) than from another page in your site does that indicate your site is failing the user, or that the user prefers to use a search engine?
If a page is a common exit point does that mean it satisfied the user need, or did it just frustrate them enough to give up? Does an elongated 'time on page' mean the content engrossed the reader or that they glazed over into catatonia?
If your total page hits go up down after a redesign does that mean you lost popularity or your site is providing the required content with a lot less clicks?
I think I could argue two opposite sides to almost anything Analytics appears to hint at - each supposition on a facet of Analytics would probably make an ideal topic for a formal debate in the vein of 'can money by happiness' or 'is honesty the best policy'
The answer is site Analytics on their own are ambiguous guides to user behaviour - you really need to observe, consult and 'know' your users.
Analytics' value is in aggregating data so you can visualise behaviours that prompts you to formulate questions like WHY IS IT DOING THAT? IS THAT A GOOD THING?
If only users could be consulted in large numbers at any time that was convenient to me.
PS GA has some tables of Google Queries mapped against how often a page from your site appeared in a SERP and how often one of your pages was clicked on, referred to as CTR (Click Through Rate). It makes for interesting perusing, maybe one approach would be to interpret user goal from the search, and then see how closely the target page matched or referred to the goal. An iterative approach that would probably improve user experience over time, but it would be difficult evaluate the impact.
Analysis of that information is making me think about using Summon's Best Bets
One thing that I'm pondering after my last blog post is referrals from Search Engines. If a page is linked to much more often from a search engine results page (SERP) than from another page in your site does that indicate your site is failing the user, or that the user prefers to use a search engine?
If a page is a common exit point does that mean it satisfied the user need, or did it just frustrate them enough to give up? Does an elongated 'time on page' mean the content engrossed the reader or that they glazed over into catatonia?
If your total page hits go up down after a redesign does that mean you lost popularity or your site is providing the required content with a lot less clicks?
I think I could argue two opposite sides to almost anything Analytics appears to hint at - each supposition on a facet of Analytics would probably make an ideal topic for a formal debate in the vein of 'can money by happiness' or 'is honesty the best policy'
The answer is site Analytics on their own are ambiguous guides to user behaviour - you really need to observe, consult and 'know' your users.
Analytics' value is in aggregating data so you can visualise behaviours that prompts you to formulate questions like WHY IS IT DOING THAT? IS THAT A GOOD THING?
If only users could be consulted in large numbers at any time that was convenient to me.
PS GA has some tables of Google Queries mapped against how often a page from your site appeared in a SERP and how often one of your pages was clicked on, referred to as CTR (Click Through Rate). It makes for interesting perusing, maybe one approach would be to interpret user goal from the search, and then see how closely the target page matched or referred to the goal. An iterative approach that would probably improve user experience over time, but it would be difficult evaluate the impact.
Analysis of that information is making me think about using Summon's Best Bets
Labels:
Google Analytics,
Library Web Site,
Summon,
UX
Thursday, July 11, 2013
Google Analytics 101: tracking down causes of page hit anomalies
I'm no Google Analytics guru, by any stretch, but over time my understanding and GA's powers seem to be incrementally increasing. This post is about how GA helped me understand why a particular page ranks high in page hits on our site. If you are not very familiar with GA it may help you a little.
I'm preparing to revamp our web site to work with new responsive web design templates - these will significantly change the access points to our information architecture, but not the architecture itself. Anyway, part of my prep is confirming what clients are accessing most often and greasing the path to it.
This page comes to my attention:
Types of Information Sources - Primary, Secondary, Tertiary & Refereed Journals
Pretty dry supplementary information for information literacy programs I thought. Might get a few clicks at the start of each semester, maybe.
According to GA it was the twelfth most popular page on our website in the first 6 months of 2013 (of currently 1106 pages). Over 12,000 unique page hits.
'Oh noes' I think. Do I have to put a link to it in a prominent place? Who is using this. Why?
So first I use GA to get a sense of how people are getting to this page, using the content and navigation summary features (see screencast below)
So what can I learn about why people are being referred to a particular page? What does GA tell us about Google search referrals? Using Traffic Sources, Landing Pages and Search/Organic and Keywords ('nother screencast)
Mystery solved, that particular page appears at the top the Google SERP for types of information. I can with confidence not worry about whether it should be more prominent in our site structure and nav - the vast majority of use is from a Google search done by the wider public.
Lesson learned - don't accept page hits the concrete truth about how your primary clients are using your site.
Thank you Mister Google.
I'm preparing to revamp our web site to work with new responsive web design templates - these will significantly change the access points to our information architecture, but not the architecture itself. Anyway, part of my prep is confirming what clients are accessing most often and greasing the path to it.
This page comes to my attention:
Types of Information Sources - Primary, Secondary, Tertiary & Refereed Journals
Pretty dry supplementary information for information literacy programs I thought. Might get a few clicks at the start of each semester, maybe.
According to GA it was the twelfth most popular page on our website in the first 6 months of 2013 (of currently 1106 pages). Over 12,000 unique page hits.
'Oh noes' I think. Do I have to put a link to it in a prominent place? Who is using this. Why?
So first I use GA to get a sense of how people are getting to this page, using the content and navigation summary features (see screencast below)
So what can I learn about why people are being referred to a particular page? What does GA tell us about Google search referrals? Using Traffic Sources, Landing Pages and Search/Organic and Keywords ('nother screencast)
Mystery solved, that particular page appears at the top the Google SERP for types of information. I can with confidence not worry about whether it should be more prominent in our site structure and nav - the vast majority of use is from a Google search done by the wider public.
Lesson learned - don't accept page hits the concrete truth about how your primary clients are using your site.
Thank you Mister Google.
Subscribe to:
Posts (Atom)